620137 г. Екатеринбург
ул. Комсомольская 6е, офис 213
e-mail:
[email protected]
+7 (343) 382-44-94
+7 (982) 660-660-8


Статьи
Social Media Privacy Against Neural Networks and Deepfakes
16.09.2026
The toggle switch promises secrecy. When a user sets their profile to "friends only", the platform assures them that their photographs, thoughts and connections are shielded behind a digital wall. Yet this wall is designed to block human eyes, not machine vision. As open-source neural networks become increasingly sophisticated, the gap between what a privacy setting restricts and what an algorithm can extract is widening dangerously. The rise of accessible deepfake software—tools that anyone can download and run on a consumer-grade graphics card—has turned casual social media imagery into a raw material for synthetic media manipulation.
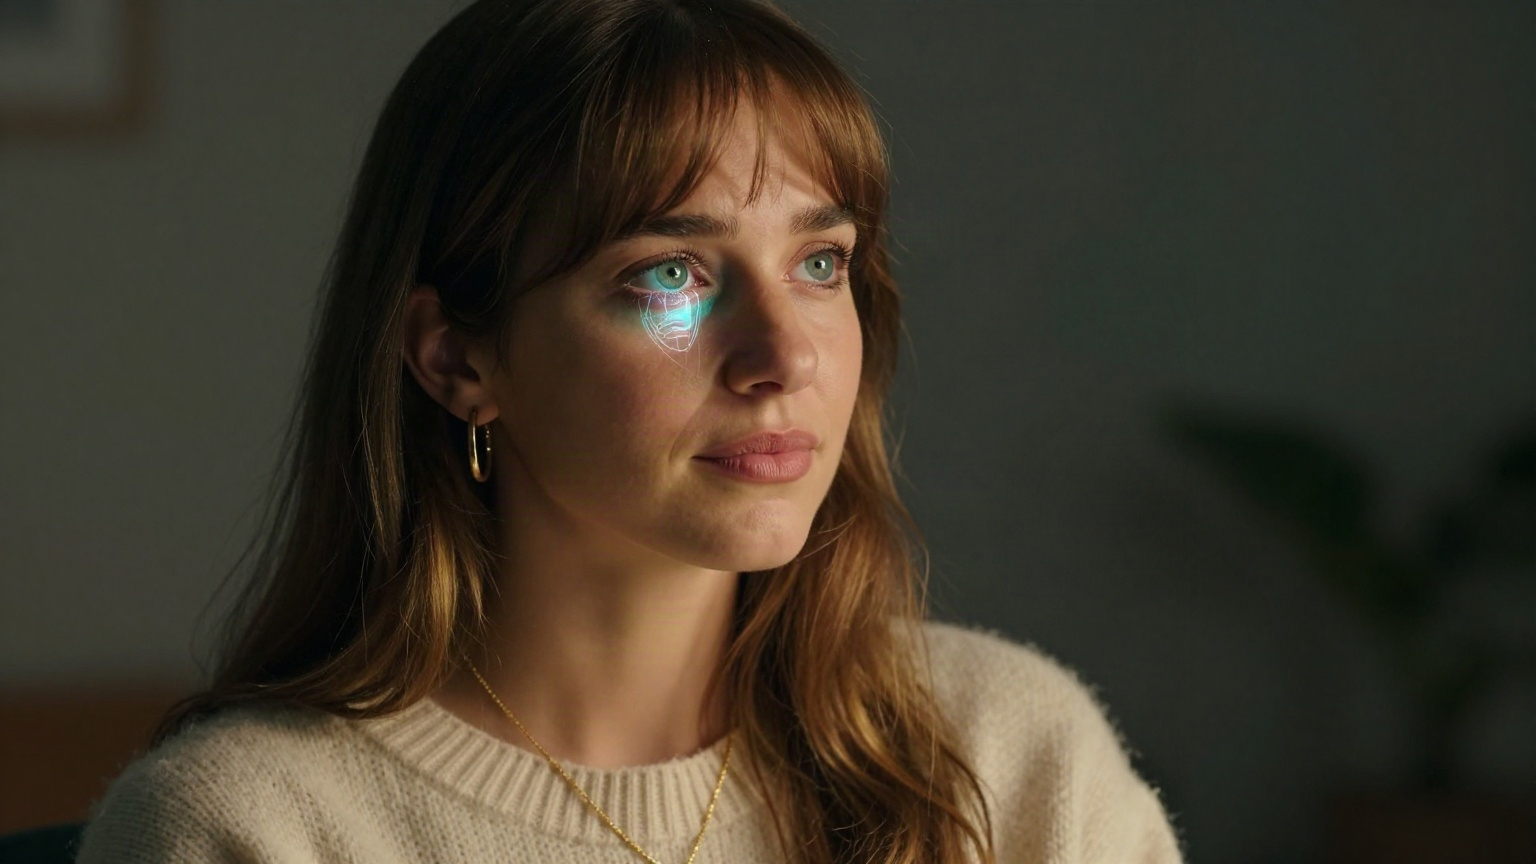
The illusion of the locked profile
Standard privacy settings operate on a binary model of access: either a viewer is permitted to see a post, or they are not. This framework assumes the primary threat is a stranger scrolling through a feed. Neural networks do not scroll. They scrape, catalogue and process data at scale, often bypassing the front-end presentation layers that privacy settings govern. If a platform's API inadvertently exposes image URLs, or if a dataset is compiled before a user tightens their settings, the neural network already has what it needs. Furthermore, a locked profile does not control the copies of images that https://slygen.ai/features/generation/hentai reside on other servers, in search engine caches, or in the albums of friends who remain publicly visible. The "friends of friends" setting, a default on many platforms, exponentially increases the surface area for automated scrapers to harvest facial data without ever triggering a human privacy concern.
How deepfake software exploits accessible data
The mechanics of modern deepfake generation rely on abundance and variance. To convincingly map one face onto another, a neural network—typically a generative adversarial network or an autoencoder architecture—requires a spectrum of angles, lighting conditions and expressions. Historically, this demanded a targeted effort to gather reference material. Today, an individual can download deepfake software from an open-source repository and feed it a folder of images scraped from social media. A public Instagram grid, a LinkedIn professional headshot, or an untagged photo on a relative's public album often provides sufficient variance. The network trains on these faces, learning the geometry of the jaw, the shadow cast by the nose, the movement of the eyelids. Within hours, the software can generate a convincing synthetic video or image, entirely independent of the original subject's consent or awareness.
The danger is compounded by metadata. When a photograph is uploaded, it often carries EXIF data—geolocation, device information and timestamps. While major platforms strip some of this data upon upload, incomplete removal or cross-referencing with other posts can build a contextual profile that makes a deepfake more credible. A synthetic video of a person in a specific city, wearing clothes consistent with their recent posts, is far more deceptive than a detached, context-free clip.
Practical privacy adjustments that matter
Defending against this requires a shift in mindset. The objective is no longer merely controlling who sees a photograph, but minimising the volume and quality of facial data available to automated scrapers. Several concrete adjustments can significantly reduce exposure.
Securing inherently public surfaces
Profile pictures and cover photos are exceptions to most platforms' privacy rules. They are public by design, serving as a recognisable anchor for the account. This makes them the lowest-hanging fruit for scraping bots. Replacing a clear facial photograph with an illustration, a logo, or a heavily stylised image immediately removes the most accessible data point. If a professional headshot is necessary for platforms like LinkedIn, restrict the album containing other angles and casual photographs to strict, first-degree connections only. Avoid using the same headshot across multiple platforms, as this allows scrapers to easily link disparate accounts and consolidate their dataset.
Managing the extended network
A locked profile is only as strong as its weakest link. Neural networks do not need a photograph of you from your own account if they can obtain it from someone else's. When a friend tags you in a public post, your facial data escapes the boundary of your personal privacy settings. Regularly auditing tag permissions—requiring approval before a tag appears on your timeline—is a foundational step. Beyond tags, consider the broader network: any gathering, event or group where attendees post publicly becomes a potential source of training data. Politely requesting that friends avoid tagging you in public albums, or reviewing their privacy settings if they insist on posting group photographs, is an uncomfortable but necessary conversation in the current landscape.
Degradation of training data
If sharing photographs is non-negotiable, degrading their utility as training data offers a pragmatic compromise. Neural networks rely on high-resolution data to map facial landmarks accurately. Downscaling images before uploading, applying subtle compression, or intentionally lowering the resolution can obscure the fine details the algorithm needs. While this does not prevent scraping, it degrades the quality of the output, making any resulting deepfake less convincing and easier to identify as synthetic. Some researchers advocate for adversarial noise—imperceptible pixel-level perturbations that disrupt facial recognition models. While promising, these tools are often model-specific and may not withstand the next iteration of deepfake software, making them an unreliable sole defence for the average user.
Limitations and realistic caveats
No configuration of privacy settings provides absolute immunity. If a photograph has ever been public on the internet, it is reasonable to assume it has been archived. Scrapers routinely bypass terms of service, and data brokers compile facial datasets that circulate well outside the control of any single social media platform. Once an image is ingested into a neural network's training set, the process is irreversible. There is no universal "delete" key for machine learning weights that have already been adjusted in response to your face. The legal concept of the right to be forgotten holds little sway over an algorithmic model stored on an anonymous server in an unregulated jurisdiction.
Moreover, the rapid pace of open-source development means that the threshold for usable data is constantly dropping. Early deepfake software required hundreds of images; current iterations can produce passable results with just a handful. As the technology improves, even heavily restricted profiles may provide enough incidental exposures over time to satisfy a determined synthetic media creator.
Defensive habits beyond the settings menu
True resilience against neural network exploitation demands a change in sharing habits, not just toggled settings. Before uploading an image, apply a simple heuristic: if this photograph were used to generate a false statement or a compromising video, would its existence make the fabrication more credible? High-definition, well-lit portraits provide the most dangerous raw material. Casual, low-resolution, or partially obscured images are significantly less useful to a bad actor wielding downloaded deepfake tools.
Diversify visual presentation across platforms. Using the same clear headshot on every social network, forum and professional site creates a unified dataset for a scraper to easily correlate and compile. Varying the images—or omitting them where unnecessary—forces any automated system to work harder to build a comprehensive model of your face.
A necessary shift in digital hygiene
The accessibility of downloadable deepfake software has permanently altered the threat landscape. Privacy settings were designed for an era of human snoopers, not relentless, automated parsers. While adjusting settings to restrict audiences, limit tags and secure public-facing images remains essential, it is merely a baseline. The most effective defence is scarcity. If a neural network cannot find enough high-quality data, it cannot build a convincing replica. In the age of accessible synthetic media, the most powerful privacy setting is the decision not to upload the raw material in the first place.
Новости
Адрес: 620137 г. Екатеринбург ул. Комсомольская 6е, офис 213
Телефон: +7 (343) 382-44-94
Е-mail: [email protected]
